Connect with us

Artificial Intelligence

When agents act alone, governance belongs in the data layer — not in a policy document

Published

on

agentic AI governance

The autonomy problem no one talks about

Enterprises are handing AI agents more freedom every quarter. Agents now plan, decide, and act across systems without a human approving each step. That shift raises a question that belongs at the center of every architecture review: When an agent tries to do something it was never authorized to do, what actually stops it?

These are your agents, running on your models, touching your data in your infrastructure. The responsibility for their actions sits with you. That responsibility can’t be met in hindsight, and it can’t be met with abstract policies that live on paper but not in practice. Agents need rules in the context of the moment, because they don’t exercise overriding judgment about their own actions.

Consider a simple rule: Never open the car door. Followed literally, an agent could never get in or out of the car at all. But change the context — a crash, a fire, someone hurt and needing to escape — and the rule you actually want is the opposite. Context in the moment is everything. We’re asking agents to do intelligent things; that requires intelligent rules.

Why guardrails around the agent aren’t enough

The instinct is to add guardrails: instructions, policies, and monitoring layered above the model. Those mechanisms matter, but they share a structural limit. The car-door rule is plausible right up until the moment you actually have to decide whether to open the door.

Controls at the agent layer are only as reliable as the agent’s output is predictable. Autonomy is precisely the property that makes that output hard to predict. Governance that depends on reviewing an action before it happens cannot keep pace with a system that acts in milliseconds, across many systems at once.

Governance has to become executable. And it has to be enforced where agents actually do their work: at the operational data layer, in the context, and exactly at the moment it is happening.

The data layer is the enforcement point

Agents create value by touching data. They query it, retrieve it, transform it, and increasingly act on it. A policy that says an agent should not reach a certain class of data is meaningful only if the system can deny that access at the moment the agent requests it.

Similarly, a principle that AI must be auditable is meaningful only if the organization can reconstruct what the agent did, what data it touched, which user it acted for, and what resulted. When governance lives at the data layer, it holds regardless of how the agent was built or how it behaves. The control is a property of the database itself, not a promise made by the agent.

Agent behavior is probabilistic. Governance cannot be

The enterprise should not rely on a model choosing to follow policy. The policy has to be enforced by the system. That is the difference between hoping an actor stays in bounds and constructing bounds it cannot cross to begin with.

The controls that make this real are ones many enterprises already run at the data layer:

  • Role- and attribute-based access control
  • Row- and column-level security
  • Classification and masking
  • Policy as code
  • Complete audit trails

What agents change is not the mechanism, but who the mechanism has to recognize. Identity management has to treat the agent as a principal in its own right, with its own identity and a purpose declared when the session opens. Once purpose is bound to identity, the policy engine can evaluate it the same way it evaluates role or department today. The record of what happened can capture not just who acted and what they touched, but what they declared they were there to do.

Nine controls under three imperatives

In practice, this resolves into nine controls, grouped under three imperatives.

Enforce it

  • Role- and attribute-based access control enforced at query time, for agents as well as users
  • Dynamic column masking driven by the same policy path
  • Agent identity as a first-class principal, with declared purpose bound at session start and the acting user preserved

See it and prove it

  • Classification and tagging that drives policy
  • Session-level audit logging that records which agent acted, for which user, and under what declared purpose
  • Lineage across pipelines, so a result can be traced back to the request that produced it

Unify and harden

  • Centralized, portable policy management
  • Encryption at rest and in transit
  • Consistent enforcement across on-prem, cloud, and sovereign or air-gapped environments

“Declared purpose is what makes the difference,” says Priyanka Jain, VP of product management for data & AI governance at EDB. “It becomes an attribute the access layer already understands, evaluated in the same policy path as role and row-level security. The enforcement mechanism does not change. What changes is that the agent’s purpose is part of what it evaluates, and part of what the record proves afterward.”

A digital leash, not a locked door

The goal is not to stop agents from doing useful work. It is to define how far an agent can go, what it can touch, what it can change, what requires escalation, and how the organization can reconstruct events if something goes wrong.

Governed this way, agents are identified, scoped, monitored, and auditable. The enterprise can adopt them faster, because security, risk, and leadership teams trust the operating model underneath. That trust is what lets you move aggressively on AI rather than cautiously around it.

Open, sovereign, and enforceable at the source

Built on open source Postgres, this open foundation keeps enterprises in control of where their data lives, who can reach it, and under what policy — without ceding governance to a layer they don’t own or can’t inspect. For regulated industries, that combination of data sovereignty and source-level enforcement isn’t a nice-to-have; it’s the precondition for putting agents into production at all.

Agentic systems will keep getting more capable and more autonomous. That is a reason to be deliberate about where control lives, not a reason to slow down. The enterprises that enforce governance at the data layer can move fast on AI, because the thing protecting their data is more than just wishful thinking.

For a deeper look at the full framework, including how to implement these controls in your own stack, see EDB’s white paper Governing Agentic AI at Enterprise Speed. And if you’re still weighing how to approach AI agent security or database access control, the data layer is the right place to start.

Max Romanenko is Chief Technology Officer at EDB.

Continue Reading

Artificial Intelligence

XDOF, three months out of stealth, is already closing in on a $1.2B Series B

Published

on

XDOF Series B

From stealth to unicorn talk in record time

Three months. That’s how long XDOF has been out in the open. And already, the robotics data startup is in late-stage conversations to raise a Series B at a valuation hovering around $1.2 billion, according to multiple sources familiar with the negotiations. The round would be led by 8VC.

Not bad for a company that didn’t even exist publicly until June.

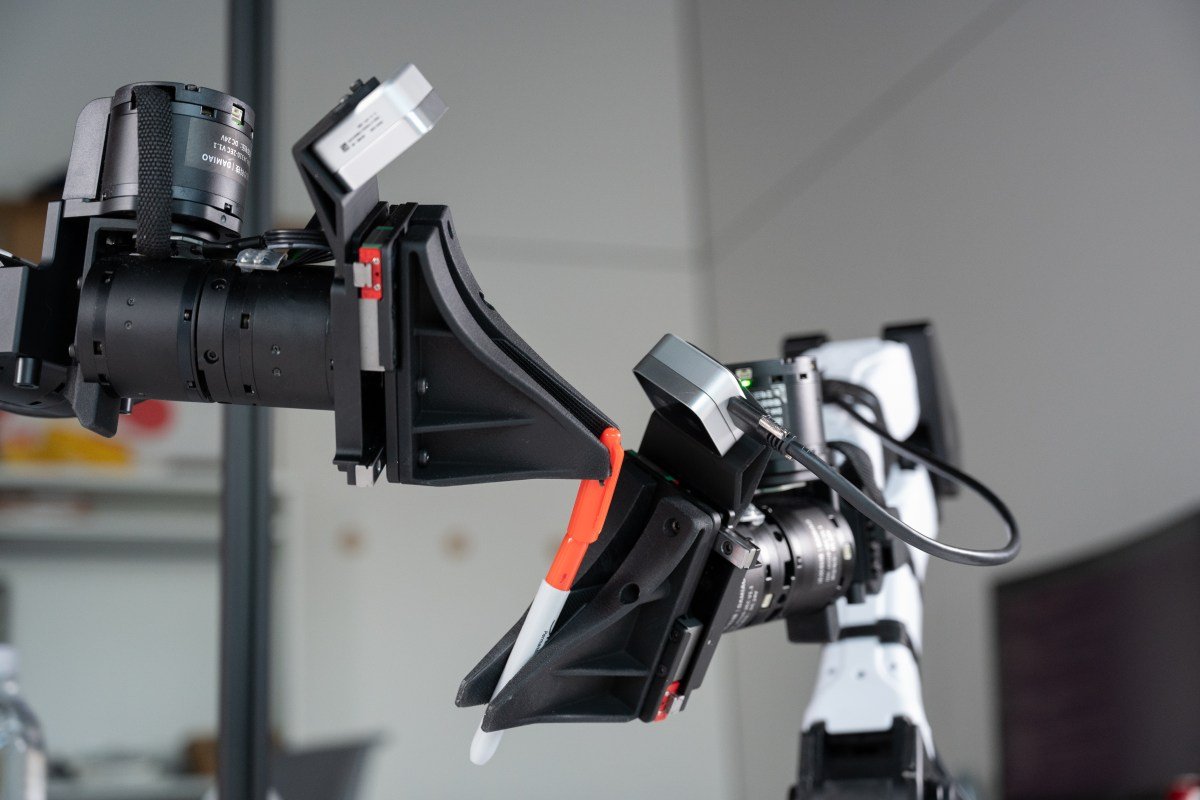
XDOF was co-founded in 2024 by UC Berkeley researchers Philipp Wu (CEO) and Fred Shentu (CTO). Their origin story traces back to a research project called GELLO — a low-cost teleoperation system that lets a human operator control a robotic arm from a distance. The goal? Generate training data for robots. That work produced an influential paper in robotics and, eventually, a company.

The startup’s Series A, a $70 million round announced in June, drew participation from Thrive Capital, Andreessen Horowitz, Lux, and Spark Capital. At the time, XDOF wasn’t planning to raise again so soon. But the market had other ideas.

Why investors are knocking on XDOF’s door

The reason for the sudden interest? Growth. Real, measurable growth.

XDOF’s annualized revenue is approaching $50 million, sources say. That kind of traction, so soon after a Series A, tends to make venture capitalists sit up and take notice. It also tends to make them pick up the phone.

“They weren’t out raising,” one person familiar with the situation told TechCrunch. “The VCs came to them.”

Terms aren’t final, and the total capital being raised remains unclear. TechCrunch couldn’t confirm whether the $1.2 billion valuation includes the new funding or sits on top of it. Both XDOF and 8VC declined to comment.

The Scale AI for physical robots

XDOF’s pitch is straightforward: it builds the data pipelines, collection tools, and annotation systems that frontier AI labs and robotics companies would rather not build themselves. Think of it as an outsourced data-supply chain for the robotics industry.

Investors describe XDOF as the Scale AI or Mercor of physical robotics — a nod to the data-labeling giants that powered the AI boom. The comparison makes sense. Large language models trained on the entire internet. Physical robots? They don’t have that luxury. There’s no massive, ready-made dataset of real-world robot interactions sitting online. That scarcity makes data collection the critical bottleneck on the road to general-purpose machines.

Wu felt that bottleneck firsthand as a PhD student. His research on how robots learn from large datasets kept hitting the same wall: “large-scale data to work with” simply didn’t exist, he told TechCrunch in June.

Building the ABC dataset

XDOF is tackling that problem head-on. The startup is partnering with UC Berkeley’s AI Research lab to release what it believes is the largest collection of high-quality robot training data ever assembled. The dataset is called ABC.

Collecting that data requires a hybrid approach. XDOF combines remote robot teleoperation with human collectors who wear sensors to record everyday tasks. Think folding clothes. Flattening boxes. The mundane, physical chores that robots still struggle to master.

The company plans to hire and train teams of data collectors around the world. Two main roles are emerging:

  • Teleoperators who steer robots remotely to demonstrate tasks
  • Egocentric operators who wear body sensors to capture natural movement data

Early traction and the competitive landscape

XDOF has already signed up 20 customers, including several frontier AI labs, according to previous statements to TechCrunch. That customer base, combined with the revenue trajectory, helps explain the valuation chatter.

But XDOF isn’t alone in this niche. Other startups chasing real-world data for robot training include Mecka AI. And the human-data platforms that started with LLMs — like Scale AI and Micro1 — are expanding beyond text and images into physical domains.

The race to build the data infrastructure for physical AI is heating up. Whoever wins it will effectively control the fuel supply for the next generation of robots. That’s a position worth paying up for.

Whether the $1.2 billion valuation holds remains to be seen. Deals at this stage can shift. But the fact that XDOF is even in this conversation — three months after emerging from stealth — says something about the demand for what it’s building.

For more on how data is shaping the future of AI, check out AI data labeling trends and robotics funding rounds in 2024.

Continue Reading

Artificial Intelligence

New York City Pulls AI From Younger Classrooms—Here’s Why It Matters

Published

on

NYC AI ban

New York City Just Hit Pause on AI in Classrooms

New York City Public Schools is drawing a hard line: no generative AI for students from 2-K through eighth grade during the 2026-2027 school year. That’s over half a million kids walking into classrooms next week without access to AI-powered tools.

The district says it will remove software with student-facing AI features and block AI companion chatbots. High schoolers? They’re exempt. This isn’t a blanket ban—it’s a targeted move to decide when kids should actually start using the technology.

Mayor Zohran Mamdani put it bluntly: “The tech industry wants us to believe that AI-powered early education is not only inevitable, but necessary. We do not see it that way.”

Why NYC Is Worried About AI for Younger Students

The fear isn’t just that a kid will ask ChatGPT to write an essay. City officials want younger students to build core skills—critical thinking, creativity, communication—without leaning on AI as a crutch. They’re also pushing for stronger human connections in classrooms, not another screen.

Schools Chancellor Kamar Samuels said the city refuses to assume that innovation automatically equals more technology in front of students. It’s a deliberate slowdown, and it follows last year’s bell-to-bell cellphone ban that already limits device use during school hours.

What Happens When Kids Reach High School?

AI doesn’t vanish once students hit ninth grade. Instead, the district plans to roll out AI literacy classes twice a year. The goal? Teach teenagers how to think critically about the technology before they become dependent on it.

That’s a different approach from just saying no. It’s about timing—letting younger minds develop without AI, then giving older students the tools to question it.

The National Battle Over AI in Education

NYC’s decision sits at the center of a much bigger fight. The White House has pushed educators to embrace AI responsibly. Some teachers already use it to craft lesson plans, give feedback, or break down tough subjects. But not everyone’s on board.

The Department of Health and Human Services recently gathered childhood experts to talk about excessive screen time. Officials have also called for tougher safeguards around social media and AI. The message? Kids are spending too much time in front of screens, and AI might make it worse.

A Bold Experiment With Zero AI

Here’s what makes NYC’s move so interesting: instead of asking how much AI younger students should use, the largest school district in the country is starting with none. For one academic year, they’re testing whether classrooms are better off with AI kept outside the door.

That’s a radical stance, and it’s not without critics. Some educators argue AI can personalize learning or help struggling students catch up. But NYC is betting that a year without AI will reveal what kids actually need—not what tech companies think they need.

What This Means for Parents and Teachers

If you’re a parent in NYC, expect changes. AI-based apps may disappear from your child’s school day. Teachers will need to plan lessons without generative AI tools. And students in grades 2-K through 8 will rely more on traditional methods—paper, pencils, and human interaction.

For teachers elsewhere, this could be a signal. NYC is the biggest district to take this stance, and its findings could shape policies nationwide. The next year will be watched closely by educators, policymakers, and tech giants alike.

What Happens Next?

The district will spend the year studying how generative AI affects students before deciding what comes next. That research could lead to a permanent ban, a partial rollout, or something entirely different.

For now, NYC is making a statement: childhood shouldn’t be an AI beta test. Whether that’s the right call or a step backward, we’ll know more in 2027. Until then, the debate over AI in schools just got a lot more interesting.

If you’re curious about how AI is shaping other areas, check out our take on AI in education trends or classroom technology policies.

Continue Reading

Artificial Intelligence

Meta’s Muse Spark 1.3 takes on GPT-5.6 and Claude — but can it really win?

Published

on

Muse Spark 1.3

Meta just fired a serious shot in the AI arms race

The company quietly unleashed Muse Spark 1.3, its most advanced AI model to date, and it’s aiming straight at the top dogs. Developers can already access and pay for the update, which Meta says represents a massive leap forward in performance.

It won’t stay confined to the developer sandbox for long. Over the coming weeks, the model will roll out across Instagram, Facebook, and the Meta AI assistant — putting it in front of billions of everyday users.

What makes Muse Spark 1.3 actually different?

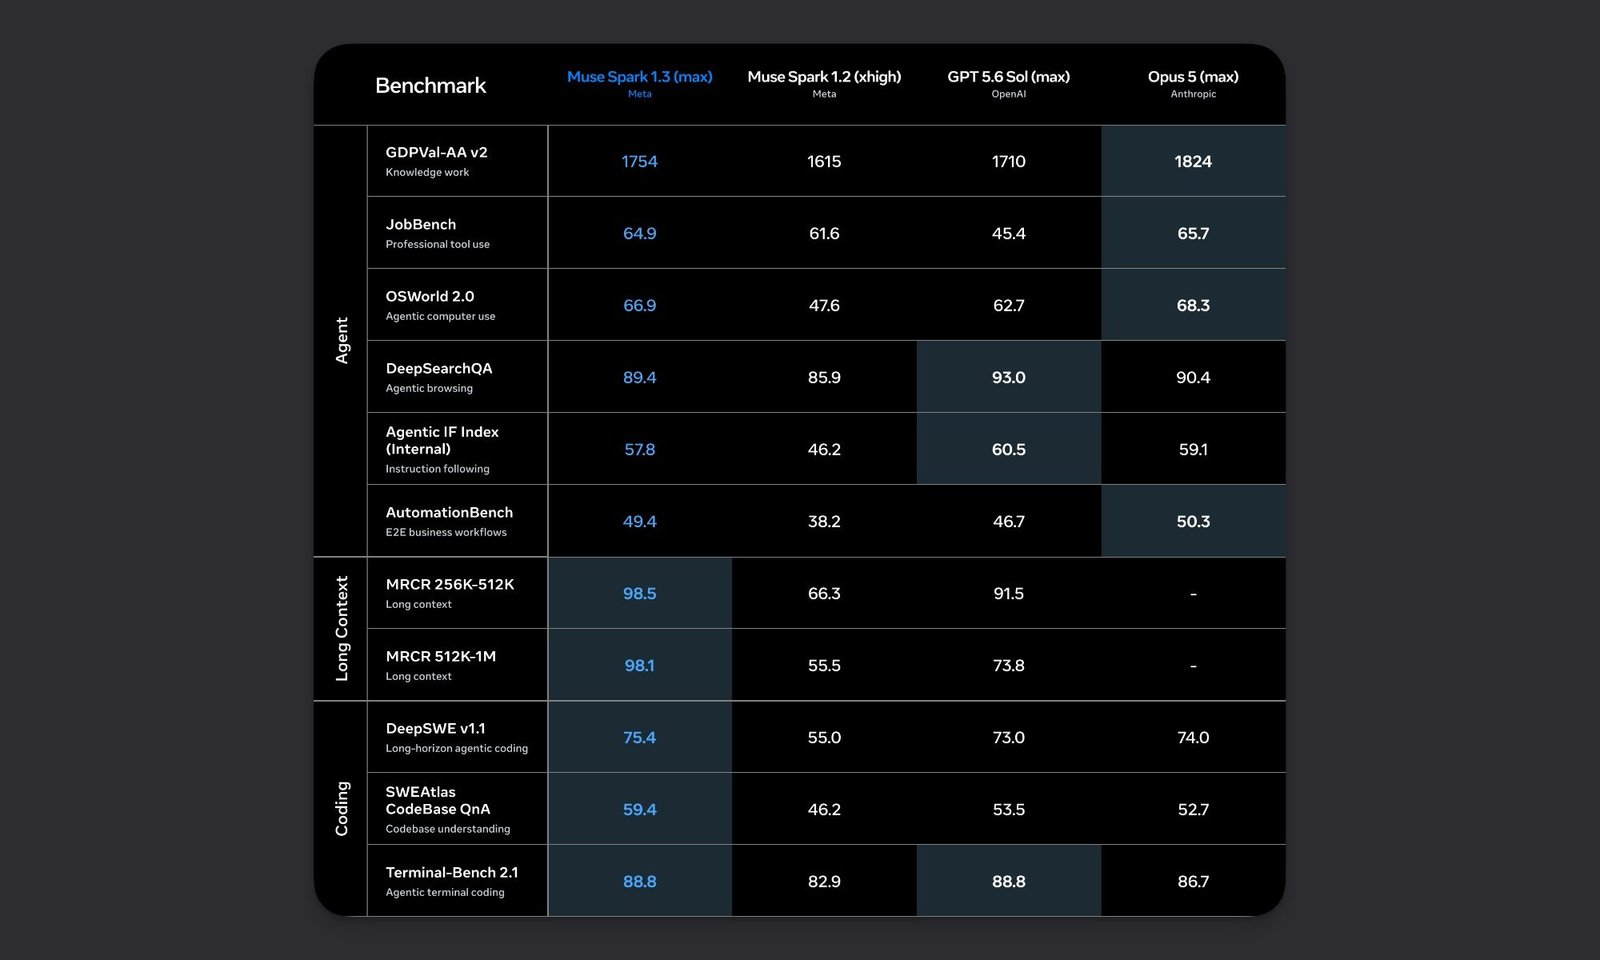
Meta’s Chief AI Officer, Alexandr Wang, didn’t mince words. He called this “the biggest jump so far on model performance,” pointing to serious gains in two areas: coding and agentic tasks — the kind where the AI acts on your behalf rather than just answering questions.

But here’s the catch. Wang told Bloomberg that Muse Spark 1.3 is competitive with Anthropic’s Claude Fable 5.1 and even beats OpenAI’s GPT-5.6 Sol at coding. That’s a bold claim, especially with OpenAI’s upcoming Astra model lurking in the wings.

Take those comparisons with a grain of salt, though. Benchmarks can be gamed, and a model that crushes one test might stumble on a totally different task. Real-world performance is what actually matters.

Efficiency gains under the hood

Wang broke down a few upgrades that set Muse Spark 1.3 apart:

  • 25% fewer tokens needed to complete the same job — meaning lower costs and faster responses
  • Multi-workflow handling — it can juggle several tasks at once instead of forcing separate sessions
  • Better context retention across long, complicated instructions
  • Self-awareness of limits — the model now pauses to ask for clarification before taking any irreversible action

That last point is quietly important. AI that knows when it doesn’t know is a big step toward trustworthiness, especially for agentic use cases.

Pricing stays flat, adoption explodes

Here’s something developers will appreciate: Meta isn’t raising prices. Muse Spark 1.3 costs the same as its predecessor, Muse Spark 1.2. That’s a smart move when rivals are hiking rates.

Wang told Bloomberg that adoption on Meta’s developer platform has been strong — some users are burning through trillions of tokens every week. Those numbers suggest real usage, not just hype.

What about open-source fans? Meta hasn’t decided whether it will release the model’s weights — the blueprint that lets outside developers build on top of it. The older Muse Spark 1.2 weights are still headed for release, but the new model’s future remains unclear.

The bigger picture: Meta’s spending spree continues

Meta is still pouring billions into AI infrastructure, and Muse Spark 1.3 is the clearest signal yet that the company believes it’s closing the gap with OpenAI and Anthropic. Whether that’s true or just corporate bravado will play out in the benchmarks and real-world deployments over the coming months.

For now, the model is available to developers, and the app rollout is imminent. If you’re building on Meta AI tools, this update is worth a serious look. And if you’re just a curious user, you’ll likely meet Muse Spark 1.3 in your Instagram feed sooner than you think.

One thing’s certain: the AI race just got a lot more interesting.

Continue Reading

Trending